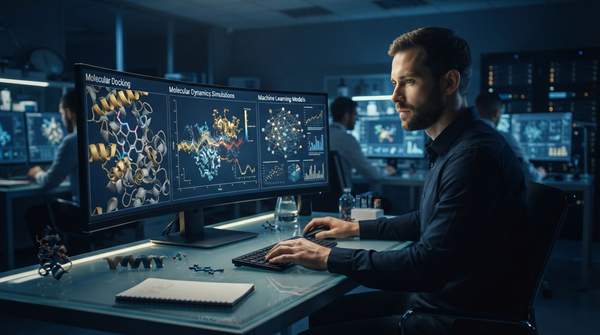
Drug discovery researchers navigate a complex landscape of computational methods, each offering distinct capabilities for identifying and optimizing potential drug candidates. Understanding the comparative strengths and weaknesses of molecular docking, molecular dynamics (MD) simulations, and machine learning (ML) models is essential for making informed decisions across critical stages such as virtual screening, lead optimization, and predicting drug-target interactions.
Computational approaches are transforming drug discovery, shifting the paradigm from traditional trial-and-error to intelligent design. These methods accelerate the process by providing deep insights into molecular interactions and predicting the efficacy of compounds, thereby reducing the extensive time and resources typically associated with experimental methods like X-ray and NMR for structure determination, as noted in a *PMC* article. The integration of techniques like machine learning, structural biology, and molecular dynamics simulations now enables researchers to generate novel proteins, predict their structures with atomic precision, and simulate their behavior in realistic biological environments, according to *Drug Discovery News*.
Molecular Docking: Principles, Strengths, and Limitations
Molecular docking is a foundational computational technique in structure-based drug discovery (SBDD), primarily employed for virtual screening. This method computationally screens vast libraries of commercially available chemical compounds against target proteins with known or predicted 3D structures. Its core principle involves predicting the optimal binding poses and affinities of small molecules (ligands) within a protein's active site, aiming to identify promising drug candidates, as detailed in *PMC*.
A significant strength of molecular docking lies in its computational efficiency. Its scoring functions are fast and approximate, making it highly suitable for rapid, large-scale virtual screening of millions of compounds to quickly narrow down a preliminary set of potential hits. However, this efficiency comes with inherent limitations. Traditional docking methods often rely on static representations of protein structures and employ simplified scoring functions. This reliance can lead to inaccuracies, particularly when dealing with flexible proteins or dynamic binding interactions, where the static model fails to capture the true conformational changes and complex binding mechanisms, according to research in *PMC*. Consequently, while excellent for initial filtering, docking may not provide the high reliability needed for later-stage lead optimization where precise interactions are critical.
Molecular Dynamics Simulations: Capturing Dynamic Interactions
Molecular dynamics (MD) simulations offer a more sophisticated approach by modeling the time-dependent movement of atoms and molecules. Unlike the static snapshots provided by docking, MD simulations capture the dynamic nature of molecular interactions, providing realistic insights into protein flexibility, conformational changes, and ligand binding. This capability is crucial for gaining a deep understanding of complex drug-target interactions and is particularly valuable for refining lead compounds during the optimization phase, as highlighted in a *PMC* publication.
Researchers at North Carolina State University emphasize that MD calculations involve all-atom simulations, illustrating how a compound moves and interacts within a protein's binding pocket. This dynamic 3D information is vital because chemical compounds are not rigid; they move, vibrate, and engage in dynamic intermolecular interactions with proteins once docked. Such dynamic interactions are often missed by models that only consider 2D or static 3D structures. While MD simulations provide a profound understanding of these intricate interactions, their high computational cost makes them impractical for initial, large-scale virtual screening of vast compound libraries. Methods for free energy calculation, often associated with MD, are computationally expensive, limiting their applicability for screening a large set of compounds, according to *PMC*.
Machine Learning Models: Pattern Recognition and Predictive Power
Machine learning (ML) models have emerged as powerful tools in drug discovery, excelling at identifying and extracting complex patterns from vast datasets. These models significantly enhance the accuracy of predictions across various stages, including virtual screening, lead optimization, and predicting drug-target interactions, as discussed in *PMC*. ML models are adept at predicting molecular properties and can be integrated with other computational methods to create more accurate predictive models for drug candidates.
Deep learning models, a subset of machine learning, are particularly effective at extracting intricate patterns from extensive datasets, thereby providing a more reliable foundation for drug discovery, according to research in *PMC*. For instance, ML can be combined with molecular dynamics and molecular docking to identify potential inhibitors, as demonstrated in a study that identified PLpro inhibitors among existing drugs, according to research published in *MDPI*. This approach leverages ML's ability to learn from diverse data, including calculated and experimental molecular properties based on molecular mechanics optimized geometries, to improve predictions and guide modulator design, as noted in *PMC*.
Comparative Analysis: Docking, MD, and ML Across Drug Discovery Stages
Each computational method—molecular docking, molecular dynamics simulations, and machine learning models—presents distinct advantages and disadvantages across the various stages of drug discovery:
-
Virtual Screening
Molecular docking is highly efficient for initial, large-scale virtual screening due to its speed and approximate nature. It allows researchers to rapidly evaluate binding affinity across millions of compounds, serving as a quick filter. However, its reliance on static protein structures and simplified scoring functions can lead to inaccuracies, particularly for flexible proteins or complex binding mechanisms. Machine learning models also contribute to virtual screening by leveraging their ability to learn from large datasets to predict molecular properties and enhance the accuracy of docking predictions. Molecular dynamics, due to its high computational cost, is generally impractical for initial large-scale virtual screening.
-
Lead Optimization
Molecular dynamics simulations are crucial for lead optimization because they provide a deep understanding of dynamic drug-target interactions and protein flexibility. This dynamic insight is essential for refining binding modes and optimizing lead compounds for improved efficacy and specificity, offering higher accuracy for flexible systems. Machine learning models contribute to lead optimization by predicting molecular properties and refining candidates based on learned patterns from complex datasets, often enhancing the accuracy of docking predictions. Molecular docking, while useful for initial screening, is less reliable for the precise, dynamic changes required in lead optimization due to its static nature.
-
Predicting Drug-Target Interactions
Molecular docking provides a fast, approximate evaluation of binding poses and affinities, offering a preliminary understanding of how a ligand might interact with a target. Molecular dynamics simulations offer a more realistic and detailed view by capturing the dynamic 3D interactions, including conformational changes in both the ligand and the protein, providing a deeper understanding of molecular interactions. Machine learning models excel at predicting drug-target interactions by identifying complex patterns in vast datasets, often significantly enhancing the accuracy of predictions made by other methods, including improving docking predictions.
Synergistic Integration: Towards Hyper-Predictive Models
The limitations inherent in traditional computational methods, such as molecular docking's reliance on static structures and simplified scoring functions, can be effectively addressed through the synergistic integration of different approaches. Researchers at North Carolina State University have demonstrated that combining molecular dynamics simulations with machine learning techniques can create more accurate, "hyper-predictive" computer models for drug discovery. This integration allows for a more comprehensive and reliable understanding of potential drug candidates.
Traditional methods like quantitative structure-activity relationship (QSAR) modeling and molecular docking primarily depend on 2D and static 3D structural information. However, these methods often fail to capture the dynamic 3D interactions—the movement, vibration, and intermolecular interactions—that occur when a chemical compound engages with a protein's binding pocket. By incorporating the results of all-atom molecular dynamics calculations into machine learning models, researchers can account for these crucial dynamic aspects, leading to significantly improved predictive accuracy. This integrated approach is particularly valuable when narrowing down a small number of analogues in later stages of drug development, where extremely high accuracy is paramount. Deep learning models, in particular, can extract complex patterns from vast datasets, further enhancing the accuracy of predictions when combined with dynamic simulation data, as noted in *PMC*.
Sources
- Computational Methods in Drug Discovery - PMC — PMC
- Drugdiscoverynews
- Integrated Molecular Modeling and Machine Learning for Drug Design - PMC — PMC
- Decoding the limits of deep learning in molecular docking for drug discovery - PMC — PMC
- Researchers Use Molecular Dynamics and Machine Learning to Create ‘Hyper-predictive’ Computer Models for Drug Discovery | Chancellor's Faculty Excellence Program | NC State University — Facultyclusters
- MDPI