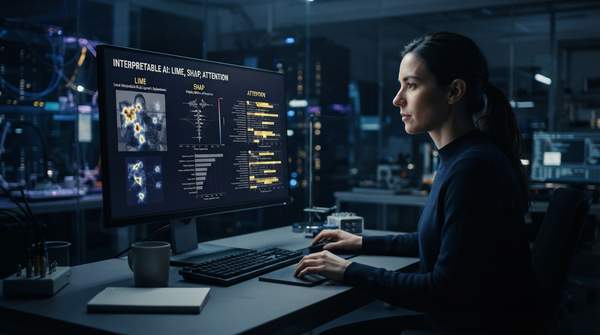
For researchers who need to interpret complex neural network decisions, the choice between LIME and SHAP comes down to one central trade-off: speed versus robustness. LIME delivers fast, local explanations for individual predictions by fitting a simple surrogate model around a single instance, but those explanations can be unstable across repeated tests. SHAP, grounded in cooperative game theory, produces consistent feature attributions that work both locally and globally, at a higher computational cost. A comparative study presented at an IEEE conference frames the decision exactly this way: LIME excels at quick local explanations that are easy to implement, while SHAP offers more robust and global insights despite its computational overhead.
Introduction to Explainable AI: LIME and SHAP
Complex neural networks achieve strong predictive performance, but their internal decision logic is opaque to the scientists who rely on them. Explainable AI (XAI) methods address this gap by attaching interpretable outputs to otherwise black-box models. Two techniques dominate practical use in scientific research: LIME (Local Interpretable Model-agnostic Explanations) and SHAP (SHapley Additive exPlanations). Both are post-hoc and model-agnostic, meaning they can be applied to any trained machine learning model without modifying it, as a perspective paper on the two methods notes.
The distinction that matters most for researchers is scope. Local interpretability explains why a model made one specific prediction for one specific instance. Global interpretability characterizes how the model behaves across an entire dataset. LIME is fundamentally a local method; SHAP spans both. This difference in scope, together with a difference in stability and cost, drives the entire selection decision.
Both methods have proven their value in applied scientific settings. A study in the electronics research literature describes how SHAP and LIME were applied together to provide global and local explanations of model predictions in wastewater treatment research, where machine learning models such as artificial neural networks, gradient boosting machines, and random forests predicted variables including BOD and TSS from multi-year operational data. The interpretability layer revealed the most influential features driving those predictions, turning an opaque predictor into a source of scientific insight.