The Four Applications in Detail
1. Literature Synthesis
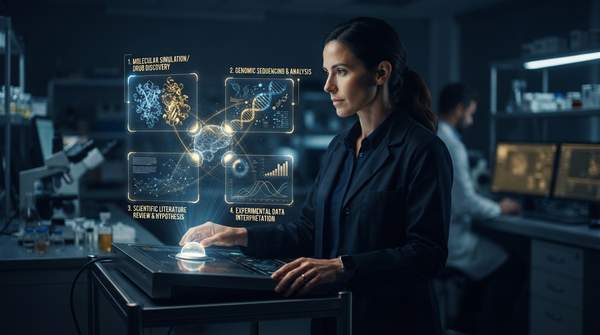
Synthesis is the most mature and lowest-risk entry point. The npj Artificial Intelligence authors count literature summarization among the earliest convenience tasks LLMs performed well, and the arXiv review identifies literature synthesis as a stage where models "meaningfully accelerate research workflows." For a researcher facing thousands of papers, an LLM can compress the first pass from weeks to hours.
The limitation is accuracy at the margins. CAS's Ayala explains that even with high-quality training data, narrow scientific topics are underrepresented, so models "struggle to go beyond broad semantics and understand nuanced, specific information." In a domain where, as the npj authors put it, "scientific processes and discoveries require high standards of truthfulness, complex reasoning, and interpretability," a summary that is fluent but subtly wrong is worse than no summary. Every claim an LLM extracts must be verified against the source before it enters your own writing.
2. Hypothesis Generation
This is the most ambitious application. The Nature review frames hypothesis generation as a way AI helps scientists "gain insights that might not have been possible using traditional scientific methods alone," and the npj perspective describes LLMs as emerging aids in hypothesis generation and experimental design. The value proposition is connection-finding: surfacing patterns across literatures no single human could hold in mind.
The ethical exposure is different in kind from synthesis. Because an LLM's suggestions are shaped by its training data, biases in that data can steer which hypotheses get proposed — and which populations, questions, or methods get ignored. And because the reasoning process is opaque, a researcher cannot audit why a model proposed a given hypothesis, which makes independent scientific justification non-negotiable. The npj authors argue that the community's "increasing recognition and communication of these limitations of LLMs is essential to enabling solutions while also limiting expectations." Treat model-generated hypotheses as leads to test, never as evidence.
3. Data Analysis
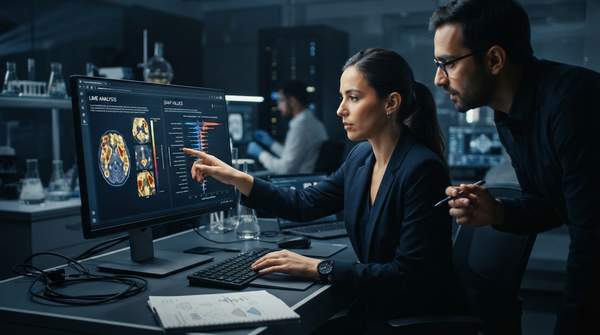
The strongest task-level evidence sits here. A computational social science review by Surendrabikram Thapa and colleagues in Social Network Analysis and Mining explores LLMs' potential to "revolutionize data analysis and content generation" in that field. The medical evidence goes further: the PMC human validation study concluded that LLMs "can effectively and efficiently process some large social media–based health-related data sets and extract themes comparable to human researchers," with promise for "greatly lowering the time and cost of analyses" — while explicitly not claiming human-level accuracy.
The risks scale with the stakes. A related arXiv review of medical applications notes that LLMs enable processing of large, heterogeneous datasets at previously unattainable scale, but that the high-stakes nature of medical contexts amplifies concerns about data quality, patient privacy, model reliability, and ethical accountability. The Thapa review adds the operational dimension: computational resource requirements, data management, and workflow integration are practical hurdles practitioners must navigate. If your data involves human subjects, those constraints belong in your IRB conversation, not just your compute budget.
4. Scientific Writing
Writing assistance is where adoption is most visible — and most measurable. Stanford HAI reports on research by James Zou's team detecting LLM-written content in peer reviews: certain words — "commendable, innovative, meticulous, pivotal, intricate, realm, and showcasing" — spiked in frequency coinciding with ChatGPT's release, and are much more likely to be used by LLMs than by humans. That a detectable stylistic fingerprint exists at scale tells you how embedded these tools already are in scientific communication.
The capability question is not settled. The PMC comparison of LLMs answering scientific questions found significant performance differences among models, and its own authors labeled their conclusions preliminary given a limited number of exam questions, calling for larger datasets, broader disciplinary coverage, and replication with independent blinded evaluators. Reliability varies by model and by question — which means an LLM-drafted passage cannot be assumed scientifically accurate because it reads well. The reviewers' ethical feedback in that same paper emphasized explicit disclosure as the mechanism for maintaining integrity and trust in AI-assisted findings.