For an industrial biotechnologist planning an enzyme engineering project, the single most consequential early decision is which of the three core synthetic biology strategies to pursue: directed evolution, rational design, or computational design. The right choice depends less on which method is fashionable and more on two practical questions: how much you already know about your enzyme's structure and mechanism, and what your laboratory can realistically screen or simulate. Directed evolution demands no prior structural knowledge but requires high-throughput screening capacity. Rational design predicts outcomes from established structure–function relationships. Computational design, including de novo protein design, leans on in silico tools to accelerate enzyme development. This guide sets out how each strategy works, what it requires, and how to match one to a specific industrial goal.
Introduction to Enzyme Engineering Strategies
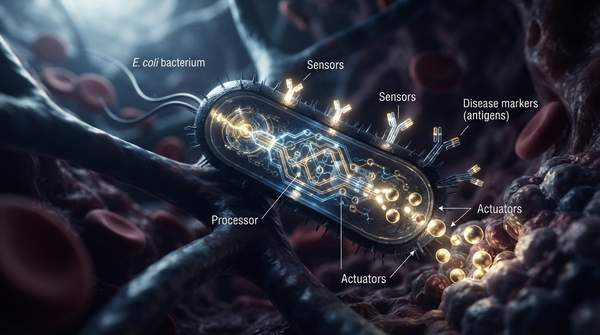
Enzymes sit at the heart of sustainable industrial biotechnology, catalyzing reactions under mild conditions that would otherwise demand heat, pressure, or harsh chemistry. But natural enzymes rarely arrive optimized for an industrial process: they may be too slow, too fragile under process conditions, or insufficiently selective for a desired substrate. Reviews of synthetic biology tools note that modifying microbial enzymes with these approaches enables faster and more efficient production than traditional strain development alone.
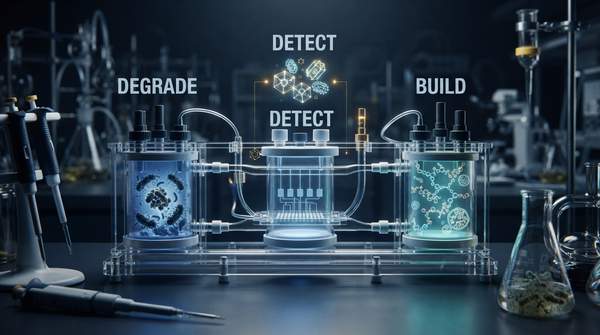
The three strategies occupy different points on a knowledge spectrum. Directed evolution works when you know little and can screen much. Rational design works when you know much and want predictable changes. Computational design sits in between and beyond, using prediction to guide experiments or to create proteins with functions that have no natural precedent. The literature also describes semi-rational and hybrid approaches that combine elements of these strategies, and several sources explicitly frame computational tools as complements to experimental methods rather than wholesale replacements for them.
Directed Evolution: Mimicking Nature's Process
Directed evolution reproduces Darwinian selection at laboratory scale. In a typical experiment, the gene encoding the macromolecule of interest—whether a protein or an RNA aptamer—is randomized and expressed in a suitable host. The resulting library of variants is then screened for the desired property, and the best performers become the starting point for the next round of diversification and selection.
What makes this strategy distinctive is what it does not require. As a review of directed evolution as a synthetic biology tool emphasizes, the method does not demand detailed functional, structural, or mechanistic knowledge of the biological system beforehand. This is its decisive advantage in complex systems: the same review observes that rational design has achieved limited success on such problems precisely because knowledge of complex biological systems is incomplete, whereas directed evolution sidesteps that gap entirely.
The track record of the method spans activity and stability improvement in individual biocatalysts, the engineering of biosynthetic pathways, the tuning of regulatory systems and logic circuits, and the development of complex phenotypes in industrial host organisms. One concrete example comes from biofuel production: a review notes that optimizing the enzymatic activities of pathway components and regulating expression levels across a metabolic pathway is essential for maximal product yield, and that directed evolution has proven effective in this setting—including work by the Liao group demonstrating production of higher alcohols from E. coli through a 2-keto acid-based pathway. The practical caveats are real, though: outcomes typically arrive through incremental improvement over multiple rounds of mutagenesis and screening, which requires sustained screening infrastructure.
Rational Design: Knowledge-Driven Engineering
Rational design inverts the logic of directed evolution. Instead of generating variation blindly and letting selection find winners, the practitioner starts from a library of well-understood, well-characterized modular biological parts—genes and proteins whose functions are known—and assembles new systems with predictable, reliable outcomes. The approach echoes the founding ambition of synthetic biology: as one synthesis described it, scientists in the early days envisioned building biological systems the same way engineers build computers and physical systems.
In enzyme engineering terms, rational design means targeted modifications made with a specific predicted outcome in mind: a mutation chosen because the structure suggests it will, say, reshape an active site or stabilize a loop. Its success is directly tied to the depth and accuracy of the prior structural and mechanistic knowledge about the system. When that knowledge is solid—when the enzyme's structure is solved and its mechanism mapped—rational design offers predictability that random approaches cannot match.
The limitation is equally direct. The same literature that champions directed evolution for knowledge-poor systems notes that rational design has historically struggled there, because the predictions are only as good as the understanding behind them. For an industrial enzyme whose structure is unknown, or whose mechanism involves poorly characterized dynamics, rational design alone may leave the engineer guessing.
Computational Design: In Silico Enzyme Engineering
Computational design brings the prediction problem into software. A review of microbial enzymes and their synthetic biology applications frames computational protein design as a technical addition to synthetic biology for de novo protein design and the study of functional aspects of designed proteins. In practice, this means using algorithms and structural models to predict which sequences will fold and function as intended, and to design enzymes or pathways before any wet-lab work begins.
The same review positions synthetic biology as a tool for predicting pathway alterations and designing production pathways for different enzymes—but it is candid that a predicted pathway does not always work as designed. That gap, the authors note, drives continued development of new computational tools to obtain more favorable outcomes for biological problems faced in industries. Computational tools are also credited with helping develop microbial enzymes faster and more efficiently than traditional approaches, including within designed consortia of microorganisms whose member interactions can be modeled.
For the practitioner, the honest picture is that computational design is powerful but fallible: predictions must be validated experimentally, and the review literature explicitly anticipates the need for iterative tool development when in silico designs underperform. Its greatest value is in combination—screening candidate designs computationally before committing screening resources, or designing functions that have no natural template at all.
Comparative Overview of Enzyme Engineering Strategies
The table below contrasts the three strategies across six decision-relevant dimensions. Use it to match your project's starting knowledge, screening capacity, and goal to the method whose profile fits: for example, whether structural data exists for your enzyme, and whether you need incremental optimization or a genuinely novel function.
| Dimension | Directed Evolution | Rational Design | Computational Design |
|---|---|---|---|
| Core principle | Mimics Darwinian selection in the test tube; iterates diversification and selection | Assembles well-characterized modular parts to achieve predictable outcomes | Uses computational tools for de novo protein design and pathway prediction |
| Key methodological steps | Randomize the gene of interest, express a variant library in a host, screen for improved traits, repeat | Targeted modifications guided by structural and mechanistic insight | Model and predict sequences, structures, and pathways in silico, then validate experimentally |
| Prerequisite knowledge | None required a priori on structure or mechanism | Detailed functional, structural, or mechanistic information is essential | Depends on computational models and databases; predictions need experimental confirmation |
| Typical outcome | Improved activity and stability, engineered pathways (e.g., higher-alcohol biofuel production in E. coli), tuned regulatory systems | New systems assembled predictably from characterized parts | Faster, more efficient enzyme development; novel designed functions |
| Primary advantage | Works in complex, knowledge-poor systems where rational design has struggled | Predictable, knowledge-driven changes | Complements or guides experiments; enables functions without natural precedent |
| Primary limitation | Incremental gains over multiple rounds; requires high-throughput screening capability | Success capped by depth and accuracy of prior knowledge | Predicted designs and pathways may not perform as designed |
Read row by row, the table clarifies the trade-off: knowledge substitutes for screening capacity, and prediction substitutes for both—but never perfectly. No single strategy dominates across all six dimensions, which is precisely why the selection question deserves structured attention before resources are committed.
Making an Informed Choice for Your Enzyme Engineering Project
Industrial biotechnologists should select an enzyme engineering strategy by aligning their project's specific goals, the available structural and functional knowledge of the enzyme, and their laboratory's screening capabilities with the distinct profiles of directed evolution, rational design, or computational design. In practice, this resolves into a short decision sequence.
First, audit your knowledge base. If the enzyme's structure and mechanism are well characterized, rational design offers the most direct route to a predicted change. If they are not, directed evolution remains the documented workhorse for complex systems. Second, audit your screening capacity: directed evolution lives or dies by high-throughput screening of variant libraries, so a laboratory without that infrastructure should weight prediction-based approaches more heavily. Third, consider whether the goal is optimization of an existing activity or a function without a natural template—the latter points toward computational, de novo approaches. Finally, remember that these are not mutually exclusive: the literature treats computational tools as complements that accelerate and guide experimental strategies, and semi-rational hybrids that blend targeted mutagenesis with library screening are a recognized middle path.
A successful strategy selection will be indicated by efficient progress in enzyme modification and the achievement of enhanced activity, stability, or specificity for the target industrial process. That is the measurable outcome to track: not which method was chosen, but whether the chosen method moves the enzyme's performance metric—yield under process conditions, thermal tolerance, or substrate selectivity—round over round toward the process target. Budget each engineering cycle against that indicator, and switch or hybridize strategies when incremental gains stall.